1. Background
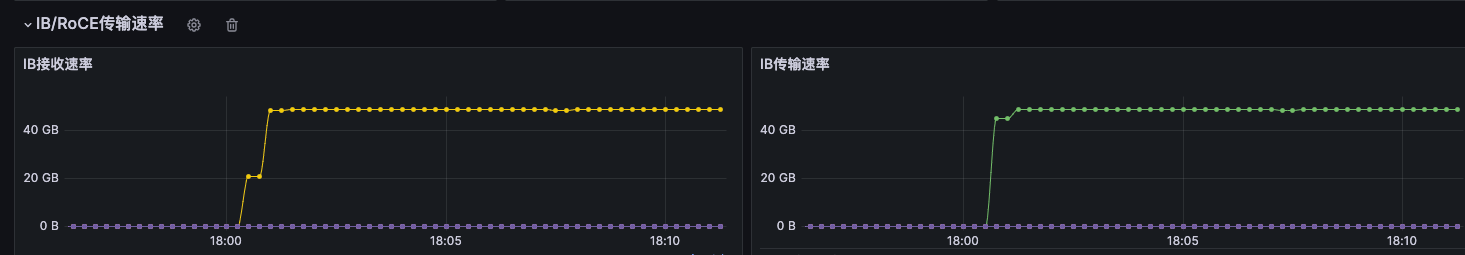
While testing the performance of NFS Over RDMA, I found that reading a 4M file could actually reach 45GB/s.
| |
Yet the disk’s 4M multi-threaded read performance is only 6 GB/s.
| |
2. NFS Over RDMA VS NFS
3. Comparing the Data Copy Paths
3.1 NFS
Transfer path:
Disk -> kernel page cache -> user-space memory (read) -> kernel network buffer (send) -> protocol stack processing -> NIC -> network -> NIC -> protocol stack processing -> kernel network buffer (receive) -> user-space memory (write) -> Disk
3.2 NFS Over RDMA
Transfer path:
Disk -> kernel page cache -> RDMA NIC -> network -> RDMA NIC -> kernel page cache (bypassing the kernel network protocol stack) -> user-space memory (write) -> Disk
3.3 Comparison
| Item | NFS (TCP/IP based) | NFS Over RDMA |
|---|---|---|
| Data copy | Requires multiple copies (user space ↔ kernel space, network buffers, etc.) | Uses RDMA to access memory directly, reducing copies |
| CPU usage | High; the CPU must handle the protocol stack and data copies | Low; RDMA offloads transmission to hardware, easing the CPU load |
| Latency | Higher; TCP/IP processing adds overhead | Low; bypasses the protocol stack and accesses via DMA directly |
| Throughput | Limited by TCP/IP and CPU processing power | High; RDMA provides higher bandwidth |
| Network protocol | Relies on the TCP/UDP transport protocol | Uses RDMA to access remote memory directly |
| Use cases | Suited to general network environments and low-cost storage sharing | Suited to high-performance computing (HPC) and large-scale distributed storage |
| Deployment complexity | Easy to deploy; works on standard Ethernet | Requires RDMA support (RoCE or InfiniBand); more complex to deploy |
| Hardware dependency | Only needs a standard NIC | Requires an RDMA-compatible NIC (such as RoCE, InfiniBand) |
4. Step-by-Step Analysis of the Transfer Path
The transfer path exercised by the FIO test:
kernel page cache -> RDMA NIC -> network -> RDMA NIC -> kernel page cache (bypassing the kernel network protocol stack) -> FIO user-space memory
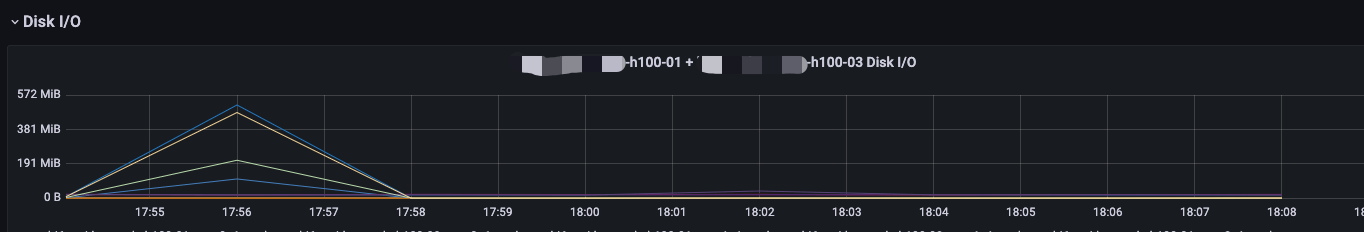
From the monitoring, you can see that during the test there is only disk activity from the previous test; after that nothing goes through the disk. The direct=1 parameter of fio only controls whether the client uses the cache; it cannot control the NFS server.
But RDMA is running at full speed, reaching 45 GB/s.
Let me test the memory read and write speed:
| |
| |
Memory read and write speeds reach 145 GB/s and 79.9 GB/s respectively, far higher than the 45 GB/s of a single RDMA NIC.
Seen this way, the bottleneck when fio tests large-file reads really is the RDMA network transfer speed.
